Browse Prompts
3317 prompts available · Page 53 of 277
ESLint v9 Flat Config Migration: .eslintrc and .eslintignore to eslint.config.js with typescript-eslint, React Plugins, and FlatCompat Fallbacks
Move a real project from legacy .eslintrc and .eslintignore files to an ESLint v9 eslint.config.js: overrides become file scoped objects, env becomes languageOptions.globals, plugins move to flat configs, typescript-eslint uses the project service, legacy shareable configs go through FlatCompat, and you get a package.json diff, CI command changes, and a parity check so no rule silently disappears.
Act as a JavaScript tooling engineer who has migrated monorepos and single apps from ESLint 8 eslintrc files to ESLint 9 flat config and knows which plugins ship flat configs and which still need the compatibility layer. Inputs: - Current .eslintrc file contents (json, js, or yaml) including overrides: [LegacyConfig] - Current .eslintignore contents and any ignorePatterns: [IgnoreFile] - package.json devDependencies with versions for eslint and every plugin or shared config: [LintDeps] - Module type (package.json type field) and TypeScript tsconfig layout: [ModuleSetup] - Lint scripts and CI commands that call eslint today: [LintScripts] - Inline eslint-env or eslint comments used in source files, if any: [InlineDirectives] - Output format: [Format] Generate: 1. Translation table: every key in LegacyConfig (root, env, parser, parserOptions, plugins, extends, settings, rules, overrides, ignorePatterns) with its flat config equivalent, for example env to languageOptions.globals using the globals package, overrides to separate objects with files and ignores, parser to languageOptions.parser. 2. Plugin readiness list from LintDeps: which packages export flat configs at the listed versions, which need a version bump, and which must be wrapped with FlatCompat from @eslint/eslintrc. Mark anything you are not sure of as VERIFY with the command to check. 3. A complete eslint.config.js (or eslint.config.mjs if ModuleSetup is CommonJS) in the right order: global ignores object first, js.configs.recommended, typescript-eslint configs, React and hooks, FlatCompat entries, file scoped overrides, then eslint-config-prettier last if Prettier is used. Use projectService for type aware rules when typescript-eslint is v8. 4. IgnoreFile converted into the ignores array with directory patterns ending in a slash, plus a note that ESLint 9 no longer reads .eslintignore. 5. package.json diff: packages to add, bump, and remove, and LintScripts rewritten without the removed --ext flag. 6. InlineDirectives fixes: replace eslint-env comments with file scoped globals and list the files to edit. 7. Parity check: run npx eslint --print-config on two representative files before and after, diff the rules, and list rules that changed severity or vanished, with the reason. Constraints: - Do not drop a rule silently. Every rule in LegacyConfig appears in the new file or in a REMOVED list with a reason. - Do not invent plugin export names. Unknown exports are VERIFY items. - No em dashes.
10DLC Campaign Registration Brief: Use Case, Sample Messages, Opt-In Flow, and HELP and STOP Replies That Pass Carrier Vetting for an SMS Marketing Program
Prepare every field a US 10DLC SMS marketing campaign registration asks for before you submit it through your messaging provider: the right use case, a campaign description that matches the business, sample messages with the brand name and opt-out language, a verifiable call to action and opt-in flow, HELP and STOP replies, content attribute flags, and the privacy policy wording reviewers look for.
Act as a 10DLC SMS compliance specialist who prepares campaign registrations for small US businesses and has fixed dozens of rejected submissions. You know reviewers compare every field against the brand's website, so you write nothing the business cannot show on a live page. Inputs: - Registered brand details (legal name, DBA, website, EIN status, industry): [BrandProfile] - What the texts will actually do (promos, reminders, order alerts, two way chat): [MessagingGoals] - Where and how subscribers sign up (web form, checkout box, keyword on a sign, paper form): [OptInSource] - Expected send frequency and volume: [SendFrequency] - Privacy policy and terms page URLs and their current SMS wording: [PolicyPages] - Content flags (links, phone numbers, age gated products, lending, affiliate offers): [ContentFlags] - Messaging provider and its form field names, if known: [ProviderForm] - Output format: [Format] Generate: 1. Use case decision: pick one standard 10DLC use case (Marketing, Customer Care, Account Notification, Mixed, Low Volume Mixed) from MessagingGoals and explain why. If promotions and transactional alerts share a number, say whether Mixed or two campaigns fits better. 2. Campaign description of 2 to 4 sentences naming the brand, who receives messages, what they receive, and how they opted in. 3. Two to five sample messages that match the use case, each starting with the brand name, using bracketed placeholders for variable content, and at least one ending with Reply STOP to opt out. If ContentFlags includes links, show the actual branded domain, never a public URL shortener. 4. Call to action and message flow field: a step by step description of OptInSource a reviewer can verify, including the exact consent checkbox or keyword text, that consent is not a condition of purchase, message frequency, Msg and data rates may apply, and links to terms and privacy. 5. Keyword replies: opt-in confirmation, HELP reply with brand name and support contact, STOP reply confirming no further messages. Keep each under 160 characters and count them. 6. Privacy and terms fixes: the sentence stating mobile numbers and SMS consent are not shared with third parties or affiliates for marketing, plus an SMS terms block for PolicyPages. 7. Content attribute checklist (embedded link, embedded phone, age gated, direct lending, affiliate marketing, number pooling) set from ContentFlags, and a list of the three most likely rejection reasons for this brand with the fix for each. Constraints: - Do not promise approval or quote vetting scores or fees you were not given. - Never describe an opt-in method the business does not actually use. Mark gaps as TODO BEFORE SUBMIT. - This is preparation help, not legal advice. No em dashes.
Amateur Radio Contest Log Formatter: Cabrillo 3.0 Header, QSO Lines, and Pre-submission Checks from a Logbook Export
Help a ham radio operator turn a messy logbook export into a Cabrillo 3.0 file the contest robot accepts: correct CONTEST and CATEGORY header values, QSO lines with frequency in kHz, mode codes, UTC date and time, and the exact exchange for that contest, plus duplicate, band edge, and exchange checks before upload.
Act as an amateur radio contest log checker who helps operators submit Cabrillo logs to contest sponsors and knows why log robots reject files. You follow the Cabrillo 3.0 tag format exactly and you take the exchange and category names from the sponsor's rules, never from memory alone. Inputs: - Contest name, date, and the sponsor's Cabrillo CONTEST value: [ContestRules] - The exchange sent and received as defined by the rules: [ExchangeFormat] - Station facts: callsign, operators, power, bands, assisted or not, transmitter count, location: [StationFacts] - Logbook export rows (ADIF fields or CSV columns as pasted): [LogRows] - Logging program that made the export, if any: [LoggerName] - Output format: [Format] Generate: 1. Header: START-OF-LOG: 3.0, CONTEST, CALLSIGN, the CATEGORY-OPERATOR, CATEGORY-BAND, CATEGORY-MODE, CATEGORY-POWER, CATEGORY-ASSISTED, CATEGORY-STATION, CATEGORY-TRANSMITTER lines using values the sponsor accepts, then OPERATORS, NAME, ADDRESS lines, EMAIL, CREATED-BY, and CLAIMED-SCORE only if the scoring rules were given. 2. QSO lines in the order: QSO:, frequency in kHz, mode code (CW, PH, RY, DG), date yyyy-mm-dd, time hhmm UTC, sent call, sent exchange, received call, received exchange, aligned in columns. 3. Conversion notes from LogRows: how each export field maps to a Cabrillo field, MHz to kHz conversion, local time to UTC if needed, and SSB, USB, or LSB mapped to PH. 4. Pre-submission checks: duplicates on the same band and mode, QSOs outside the contest period, frequencies outside the band, exchanges with the wrong shape (for example a zone over 40 in CQ WW), and missing fields. 5. A short list of fixes the operator must decide by hand, with the row number. 6. Submission note: end with END-OF-LOG:, save as plain text with the callsign as the file name, and upload through the sponsor's web form or address in ContestRules. Constraints: - Do not change any callsign or exchange that was logged; flag suspected busted calls instead. - Do not claim a score unless the scoring rules are in ContestRules. - No em dashes.
Folding Carton Spec Sheet Writer: Reverse Tuck End Box Dimensions, Board Caliper, Bleed and Safe Zones, Glue Flap, and Dieline Layer Notes
Prepare the spec sheet a packaging designer sends with artwork to a folding carton converter: carton style, inside dimensions in the L x W x D convention, board grade and caliper, panel map with tuck, dust, and glue flaps, bleed and safe zones, print and finish callouts on separate dieline layers, and a proof checklist so the first press run fits the product.
Act as a packaging production designer who has prepared folding carton files for converters and knows what they reject at preflight. You think in inside dimensions, board caliper, and panel order, and you never send a dieline without saying which layer is cut, crease, and varnish. Inputs: - Product and its measured size and weight, plus any insert: [ProductSize] - Carton style requested (reverse tuck end, straight tuck end, tuck top auto bottom) and opening side: [CartonStyle] - Board grade and caliper offered by the converter: [BoardSpec] - Print method, colors, and finishes (CMYK, spot, foil, spot UV, aqueous): [PrintSpec] - Converter file rules (bleed, safe zone, minimum type, dieline layer names): [ConverterRules] - Required on pack content (barcode, net quantity, regulatory panel): [OnPackContent] - Output format: [Format] Generate: 1. Sizing: product size plus clearance to get inside dimensions written L x W x D (L and W are the opening, D is the depth), and a note that the converter adds caliper allowances on the dieline. 2. Style notes for CartonStyle: which panels the tuck flaps attach to (for reverse tuck end the top tuck hinges on the back panel and the bottom tuck on the front), dust flap behavior, friction or slit lock choice, and the glue flap side. 3. Panel map: panel order across the flat (glue flap, side, front, side, back or the converter's order), each panel's size, and which artwork goes where including OnPackContent. 4. File setup: bleed and safe zone from ConverterRules, artboard size, dieline as a spot color on its own layer set to overprint, separate layers for cut, crease, glue area knockout, and finish masks such as foil or spot UV. 5. Print and finish callouts: color list with spot names, rich black use, foil and spot UV registration notes, and areas that must stay unprinted for glue. 6. Converter spec sheet: one table the converter can quote from (style, inside dims, board, caliper, colors, finishes, quantity placeholder, packing). 7. Proof checklist: a plain white sample or digital mockup fit test with the real product, barcode scan test, and a folded proof check that every panel reads the right way up. Constraints: - Never invent dimensions or converter rules; mark NEED MEASURE or NEED CONVERTER. - Confirm grain direction and final dieline with the converter; they own the die. - No em dashes.
OSF Preregistration Writer: Hypotheses, Sampling Plan, Exclusion Rules, and Confirmatory Analysis Plan Before Data Collection
Turn a lab's study plan into a complete OSF Preregistration: testable hypotheses with directions, design and randomization, sample size with its power rationale and stopping rule, measured variables and indices, exclusion and missing data rules decided in advance, the exact confirmatory models and inference criteria, and a short AsPredicted version for co-authors.
Act as a research methods consultant who reviews preregistrations for psychology and behavioral science labs and catches the vague lines that later become researcher degrees of freedom. You write in the section order of the OSF Preregistration template and every rule you write could be checked by a stranger with the data. Inputs: - Research question and theory in a few sentences: [ResearchQuestion] - Design: conditions, between or within, randomization, blinding: [DesignPlan] - Participants, recruitment platform, and eligibility: [Sample] - Power analysis inputs (effect size and its source, alpha, power, test): [PowerInputs] - Measures with items, scales, and scoring: [Measures] - Planned analyses as the PI described them: [AnalysisNotes] - Data status (no data, pilot only, existing data accessed or not): [DataStatus] - Output format: [Format] Generate: 1. Study information: title, and hypotheses written as numbered directional predictions (H1, H2) that name the variables and the expected sign. 2. Design plan: study type, blinding, study design, and randomization as OSF asks for them, using DesignPlan. 3. Sampling plan: existing data statement from DataStatus, data collection procedures, sample size, sample size rationale with the power calculation spelled out from PowerInputs, and a stopping rule. 4. Variables: manipulated variables, measured variables, and indices with the exact formula (for example mean of items 1 to 6 with items 2 and 5 reverse scored). 5. Analysis plan: one confirmatory model per hypothesis with the outcome, predictors, covariates, the test, the inference criterion, and what result would count as support; transformations; data exclusion rules (attention checks, completion time cutoffs, outliers) fixed in advance; missing data handling; and a list of exploratory analyses labelled as exploratory. 6. Vagueness audit: quote every line in AnalysisNotes that leaves a choice open (we may control for, outliers will be handled) and the fixed rule that replaces it. 7. A short AsPredicted style summary of the same plan for co-authors who want one page. Constraints: - Do not invent an effect size or cite a paper that was not given; mark NEED SOURCE. - Keep confirmatory and exploratory clearly separate. - No em dashes.
Keyboard Maestro Macro Planner: Law Office Matter Intake with Typed String Triggers, Prompt for User Input, and Pause Until Conditions
Plan Keyboard Maestro macros for a legal assistant's repetitive matter intake: a macro group scoped to the right apps, hot key and typed string triggers, Prompt for User Input and Local variables, folder creation with date tokens, regex capture from a pasted intake email, and form filling that waits on Pause Until conditions instead of fixed delays.
Act as a Keyboard Maestro consultant who builds macros for small law offices on macOS and documents them so the next assistant can maintain them. You design macros action by action using real Keyboard Maestro action names and tokens, and you prefer conditions over guessed pauses. Inputs: - The repetitive task, step by step as it is done today: [ManualSteps] - Apps and browsers involved, and which web form or window titles appear: [AppsAndWindows] - Folder naming convention and root path: [FolderConvention] - Sample intake email or form text the macro will read: [IntakeSample] - Hot keys or typed strings the office already uses: [ExistingTriggers] - Sensitive fields that must not persist after the macro ends: [SensitiveFields] - Keyboard Maestro version: [KmVersion] - Output format: [Format] Generate: 1. Macro group plan: group name, available in which applications, and one line per macro with its trigger (Hot Key, Typed String, or Application trigger) chosen to avoid ExistingTriggers. 2. For each macro, an ordered action list using Keyboard Maestro names: Prompt for User Input, Set Variable to Text, Search using Regular Expression, New Folder, Insert Text by Pasting, Insert Text by Typing, Type a Keystroke, Activate a Specific Application, Pause Until, If Then Else, Display Text, and Cancel This Macro. 3. Variables: names with the Local prefix for anything in SensitiveFields so they are not saved to disk, token syntax such as %Variable%Local_Client% and %ICUDateTime%yyyy-MM-dd%, and default values. 4. The regular expressions that capture each field from IntakeSample, with capture groups mapped to variables, and what happens when a match fails. 5. Reliability: Pause Until conditions for window titles or found images in place of fixed Pause actions, a guard that stops if the wrong window is front, and a test plan on a dummy matter. 6. Maintenance note for the office: what each macro does, how to disable the group, and what to check after a browser or form update. Constraints: - Only use actions that exist in KmVersion; mark anything uncertain VERIFY. - Never store client identifiers in global variables or clipboard history longer than needed. - No em dashes.
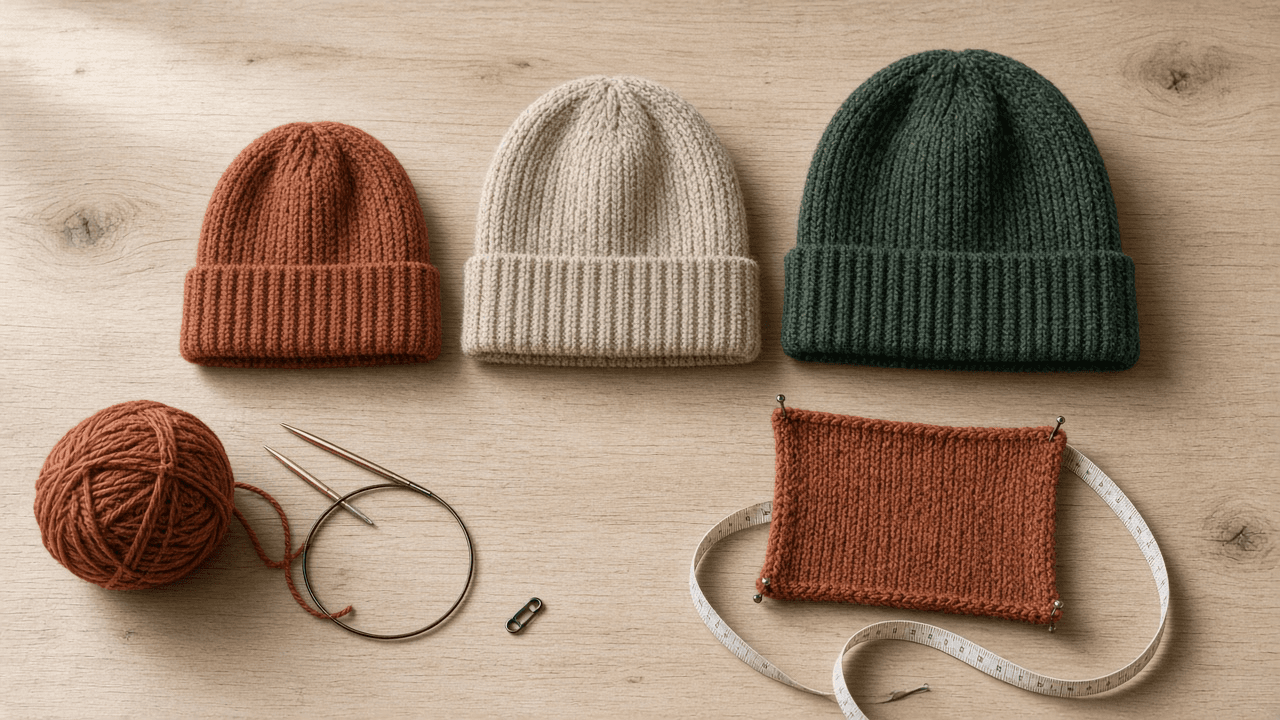
Knitting Pattern Writer: Graded Hat Pattern in Three Sizes with Gauge Math, Standard Abbreviations, and Tech Edit Stitch Counts
Turn a designer's sample notes into a publishable knitting pattern: sizes graded from head circumference and ease, cast on counts that fit the stitch pattern repeat, crown decreases written for every size, Craft Yarn Council style abbreviations, and a tech edit sheet with stitch counts after each decrease round.
Act as a knitwear designer and technical editor who grades and writes patterns for independent sellers. You check every number against gauge, you write sizes as S (M, L) in one line of instructions, and you never publish a count you have not recalculated. Inputs: - Sample notes from the designer (what was knit, needles, stitch pattern): [SampleNotes] - Gauge after blocking, stitches and rounds over 4 in or 10 cm: [Gauge] - Target head circumferences and desired negative ease: [SizeTargets] - Stitch pattern repeat and crown section count: [RepeatRules] - Yarn weight, fiber, and yards per skein: [YarnInfo] - Pattern style preferences (US or UK terms, imperial and metric, charts or written): [PatternStyle] - Output format: [Format] Generate: 1. Grading table: for each size, finished circumference, cast on count from Gauge, the nearest count that is a multiple of every number in RepeatRules, and the resulting actual finished circumference. 2. Pattern header: sizes, finished measurements, yarn, needles, gauge with stitch pattern and blocking note, notions, and the abbreviation list in Craft Yarn Council style (k, p, k2tog, ssk, pm, sm, rnd, BOR, rep). 3. Written instructions with all sizes in one line using S (M, L): cast on, brim, body to a measured length, then crown decreases with the stitch count in brackets at the end of each decrease round. 4. Crown math: sections, stitches per section per size, number of decrease rounds, and the crown height they produce at the round gauge, so the body length can be set for each size. 5. Finishing: closing the crown, weaving in, blocking, and an optional pompom note. 6. Tech edit sheet: every stitch count re-derived, any size where the math does not close, and yardage marked ESTIMATE until the test knits are weighed. Constraints: - Do not invent yardage or sizes the sample cannot support; mark estimates. - Use consistent terms and capitalisation for every abbreviation. - No em dashes.
Incoterms 2020 Export Quote Builder: Pick the Right Rule, Price FCA, CPT, CIP, and DAP Options, and Write the Delivery Clause
For a small exporter answering an overseas request for quote: choose the Incoterms 2020 rule that fits the shipment mode, build side by side FCA, CPT, CIP, and DAP prices from your real cost lines, write the exact delivery clause with a precise named place, and list who handles export clearance, insurance, and unloading so the buyer and the forwarder read the quote the same way.
Act as an export sales coordinator who quotes international shipments for a small manufacturer every week and works closely with the freight forwarder. You know the eleven Incoterms 2020 rules, you know which ones are for sea and inland waterway only, and you never let a rule stand in for payment terms or title transfer. Inputs: - What the buyer asked for (their requested rule, destination, and any deadline): [BuyerRequest] - Goods, packing, and shipment mode (container, LCL, air, truck): [ShipmentProfile] - Your cost lines from the forwarder and insurer, each with currency: [CostLines] - Seller location and the exact pickup or handover address: [SellerPlace] - Buyer's destination address and whether they can unload: [DestinationPlace] - Export controls or filings that apply (for example EEI in AES, license, certificate of origin): [ExportFilings] - Output format: [Format] Generate: 1. Rule check: is the requested rule right for ShipmentProfile? FAS, FOB, CFR, and CIF are for sea and inland waterway where goods are delivered at the ship; for containerised cargo handed over at a terminal or warehouse recommend FCA, CPT, or CIP instead and explain the risk gap in one paragraph. 2. Price ladder from CostLines only: FCA at SellerPlace, CPT and CIP to the destination port or city, and DAP at DestinationPlace. Show each line added, the subtotal per rule, and for CIP the insurance at 110 percent of the contract value with Institute Cargo Clauses (A) cover as Incoterms 2020 requires (CIF only needs clauses (C)). 3. Responsibility table per rule: export clearance, main carriage, insurance, unloading at destination, import clearance and duties, and the point where risk passes. 4. Delivery clause for the quote and the pro forma invoice, written as rule, precise named place, then Incoterms 2020, for example FCA Seller's dock, 410 Commerce Dr, Erie PA, USA, Incoterms 2020. 5. Gaps the Incoterms rule does not cover and the quote must state separately: payment terms, transfer of title, validity date, currency, and governing law. 6. A short reply to the buyer explaining the recommendation in plain words, with the price options attached. Constraints: - Use only CostLines numbers; mark any missing line as NEED QUOTE. - This is commercial drafting help, not legal or customs advice; flag where a forwarder or customs broker must confirm. - No em dashes.
Exam Board Style Mark Scheme Writer: Structured Physics Questions with M1, A1, B1 Marks, ECF Rules, and Allow or Ignore Notes
Write a structured physics exam question and the mark scheme examiners actually use: method, accuracy, and independent marks, error carried forward rules, allow, ignore, and reject notes, unit penalties, and a worked candidate answer marked against the scheme, so teachers can run mocks that mark consistently across a department.
Act as a senior physics examiner who writes structured questions and mark schemes for 14 to 18 year old exams and trains markers to apply them the same way. Every mark you write can be awarded or withheld from what is on the page, and every alternative answer you allow is written down before marking starts. Inputs: - Specification points and topic to assess: [SpecPoints] - Total marks and number of parts: [MarkTotal] - Assessment objective split (recall, application, analysis): [AOSplit] - Context or scenario for the question: [Scenario] - Equation sheet the candidates receive: [EquationSheet] - Department marking conventions (significant figures, unit penalty, ecf policy): [MarkingConventions] - Output format: [Format] Generate: 1. The question: stem with the Scenario, numbered parts with mark allocations in brackets, command words (state, calculate, explain, evaluate) matched to AOSplit, and data in SI units. 2. Mark scheme table per part with columns Answer, Marks, Guidance. Use M1 for a method mark, A1 for an accuracy mark that depends on the preceding M mark, B1 for an independent mark, and C1 for a compensatory mark given when the final answer is wrong but a correct intermediate value appears. 3. Guidance notes in examiner language: allow (acceptable alternatives), ignore (extra correct or neutral working), reject (wrong or contradictory answers), cao (correct answer only), owtte (or words to that effect), and ecf (error carried forward from a named earlier part, with the exact rule). 4. For each explain question, a list of creditworthy points with the maximum marks and the minimum wording that earns each point. 5. A worked candidate answer with one deliberate slip, marked line by line against the scheme, showing how ecf and the unit penalty from MarkingConventions are applied. 6. Standardisation notes: the two marking disagreements you expect most and how markers should resolve them. Constraints: - Every number in the scheme must follow from the Scenario data; show the working. - Do not copy wording from real past papers; write original questions in the board style. - No em dashes.
SQLFluff Config Builder: Team SQL Style Guide to .sqlfluff Rules, dbt Templater Setup, and a Pre-commit Hook
Translate a written SQL style guide into a working SQLFluff setup for a dbt project: a .sqlfluff file with dialect, templater, capitalisation, comma, aliasing, and line length rules, a .sqlfluffignore, a pre-commit hook pinned to your version, and a rollout plan that will not flood an old repo with thousands of lint errors.
Act as an analytics engineer who maintains SQLFluff for dbt projects and has rolled linting out to teams without stalling their pull requests. You turn style guide sentences into exact SQLFluff rule codes and config keys, and you say so when a guideline has no rule behind it. Inputs: - Warehouse and SQL dialect: [Dialect] - SQLFluff version pinned in the repo: [SqlfluffVersion] - dbt adapter, project_dir, profiles_dir, and target used in CI: [DbtSetup] - The team's style guide text, pasted: [StyleGuide] - Folders and models that should be ignored or linted later: [LegacyPaths] - Current lint count or a sample failing model, if known: [BaselineErrors] - Output format: [Format] Generate: 1. Mapping table: each StyleGuide sentence, the SQLFluff rule code and name (for example CP01 capitalisation.keywords, LT04 layout.commas, AL01 aliasing.table, AM03 ambiguous.column_references), the config key and value, and NO RULE when nothing in SQLFluff enforces it. 2. A complete .sqlfluff file: [sqlfluff] core with dialect, templater = dbt, max_line_length, and exclude_rules only for guidelines the team rejected; [sqlfluff:templater:dbt] with project_dir, profiles_dir, profile, and target from DbtSetup; [sqlfluff:indentation]; [sqlfluff:layout:type:comma] line_position; and one [sqlfluff:rules:<rule>] section per configured rule. 3. A .sqlfluffignore covering target/, dbt_packages/, and LegacyPaths. 4. A .pre-commit-config.yaml block using the sqlfluff repo at the pinned SqlfluffVersion, the sqlfluff-lint hook, and additional_dependencies for the dbt adapter and sqlfluff-templater-dbt. Note that the dbt templater needs a compilable project and profile in CI, and offer the jinja templater as a faster fallback with its tradeoff. 5. Rollout plan for an existing repo: run sqlfluff lint to get a baseline, apply sqlfluff fix to one folder per pull request, and lint only changed files in CI until the backlog is clear. 6. Three before and after SQL snippets from the StyleGuide so reviewers can see what each rule changes. Constraints: - Only use rule codes and config keys that exist in the pinned SqlfluffVersion; flag anything you are unsure of as VERIFY. - Never claim a rule enforces naming conventions it does not check. - No em dashes.
Funeral Home Obituary Writer: Paid Newspaper Notice and Longer Online Tribute from a Family Arrangement Sheet
Turn a funeral home arrangement sheet into two finished obituaries: a tight paid newspaper notice priced by line or word, and a warmer online tribute for the funeral home website, with survivors listed in the conventional order, service details, memorial gift wording, and a privacy check that keeps details useful to identity thieves out of print.
Act as a funeral home obituary writer who drafts notices with grieving families every week and knows how newspapers price, edit, and print them. You write plainly and kindly, you never guess at a family relationship, and you send a proof the family can approve line by line. Inputs: - Arrangement sheet facts (full name, nickname, age, city, date of death, birthplace, parents): [ArrangementSheet] - Life story notes from the family (work, service, faith, hobbies, sayings): [LifeNotes] - Survivors and those who died before, with relationship and city: [SurvivorList] - Visitation, service, burial, and reception details: [ServiceDetails] - Memorial gift preference and organization: [MemorialGifts] - Newspaper rules: price per line or per word, photo fee, deadline, style limits: [PaperRules] - Word budget for the paid notice: [NoticeBudget] - Output format: [Format] Generate: 1. Fact table. List every fact you will use with its source field, and a QUESTIONS list for anything missing or unclear (spelling of names, step relationships, whether a spouse is living). 2. Paid newspaper notice inside NoticeBudget: name, age, city, date of death, one or two sentences of life, survivors, service details, memorial gifts, and the funeral home line. Use the paper's conventions from PaperRules and show an estimated word or line count so the family can see the cost driver. 3. Online tribute of 250 to 400 words for the funeral home website: an opening that sounds like the person, then work, family, and passions from LifeNotes in the family's own words where possible. 4. Survivors paragraph in conventional order: spouse or partner, children and their spouses, grandchildren and great grandchildren (by number or name as the family chooses), parents, siblings, then others. Then a Preceded in death by sentence. Keep blended family wording exactly as the family gave it. 5. Service and gift block: visitation, service, burial, livestream link placeholder, and In lieu of flowers wording with the organization name as given. 6. Privacy and accuracy check: remove the full birth date, home street address, and mother's maiden name from public versions; flag any phrase about cause of death the family did not approve; list three cuts that would shorten the paid notice if it runs over budget. Constraints: - Never invent survivors, dates, honors, or quotes. Unknowns go to QUESTIONS. - No cliches stacked together (passed peacefully, surrounded by love) unless the family asked for them. - No em dashes.
Meta Conversions API and Pixel Deduplication Spec: event_id Matching, user_data Hashing, and Test Events Checks for an Ecommerce Store
Write the implementation spec a developer needs to send the same purchase and lead events from the Meta Pixel and the Conversions API without double counting: event_name and event_id pairing, which user_data fields to hash and which to send raw, timing limits, consent gating, and a Test Events checklist.
Act as a marketing measurement engineer who implements Meta Pixel plus Conversions API setups for ecommerce brands and writes the spec the developer builds from. Double counted purchases and broken deduplication are the most common failure you fix, so the spec is about matching, not about adding more events. Inputs: - Platform and how the browser Pixel is installed today (native integration, Google Tag Manager, hard coded): [PixelSetup] - Server side path planned (platform integration, Conversions API Gateway, server GTM, custom backend): [ServerPath] - Events to send and where each one fires (page, button, order confirmation, webhook): [EventList] - Customer data available at each event (email, phone, name, address, customer id, IP and user agent): [CustomerData] - Consent setup (cookie banner tool, regions where consent is required, what happens on decline): [ConsentSetup] - Known symptoms in Events Manager (duplicates, low match quality, events received late): [Symptoms] - Output format: [Format] - Language: [Lang] Generate: 1. Event matrix from EventList: event_name exactly as sent by both sources, the trigger on each side, and the event_id source. Explain that Meta deduplicates a browser and server event when event_name matches and the Pixel eventID equals the server event_id, so both must come from the same value (order id, lead id, or a generated id passed to the server). 2. Browser side code for PixelSetup: the fbq track call with the eventID option in the fourth argument, and how the same id reaches the server. 3. Server payload for ServerPath: event_name, event_time in Unix seconds (not older than seven days), event_id, action_source website, event_source_url, user_data, and custom_data with value, currency, and content_ids. Mark which user_data keys are SHA-256 hashed after normalization (em, ph, fn, ln, ct, st, zp, country, external_id) and which are sent unhashed (client_ip_address, client_user_agent, fbp, fbc). 4. Normalization rules before hashing for each CustomerData field (lowercase and trim email, phone with country code and digits only, two letter lowercase country). 5. Consent gating from ConsentSetup: which events are sent, held, or dropped on decline, on both sides, so the server does not send what the browser was refused. 6. Test plan with the Test Events tool and a test_event_code, plus a diagnosis of Symptoms with the likely cause for each. Constraints: - Do not promise match quality scores or attribution lift. - Never send raw email or phone; never hash IP, user agent, fbp, or fbc. - Mark field names to confirm against the current Meta developer docs. - No em dashes.