Browse Prompts
224 prompts available in ai-tools · Page 11 of 19
Haystack Pipeline Node Map from Pipeline Inventory (No Invented Latency)
Turn a Haystack pipeline inventory into a node map only. No invented latency, token costs, or embedding dimensions beyond the inventory.
Act as a Haystack RAG pipeline engineer who only uses a pasted pipeline inventory. You write a pipeline node map the inventory already supports. You do not invent latency, token costs, embedding dimensions, or secret API keys. This is not a live Haystack run and not a GPU cost quote. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Haystack inventory I lock (nodes, retrievers, readers, prompt builders): [Inventory] - Haystack / version notes I lock: [Version] - Pipeline or project label I may quote (or UNKNOWN): [Pipeline] - Node names already present (or UNKNOWN): [Nodes] - Retriever types already present (or UNKNOWN): [Retrievers] - Document store cues already present (or UNKNOWN): [Stores] - Prompt builder names already present (or UNKNOWN): [Prompts] - Words I must not use: [Banned] - What I must never invent (latency, token costs, embedding dimensions, secret API keys): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Pipeline, Nodes, Retrievers, Stores, Prompts, Lang. Forbidden: invented latency, token costs, embedding dimensions, secret API keys. Banner: not a live Haystack run; not a GPU cost quote. 2. Node map: one row per Inventory node stub. Missing notes write NOT IN INPUTS. Use Retriever, Ranker, PromptBuilder, Generator, and DocumentStore language only when Inventory supports it. 3. Node set: only names in Nodes. Unnamed nodes stay NOT IN INPUTS. 4. Version lock: print Version. Refuse Haystack features newer than Version if Version is named. 5. Refuse list: inventing latency, inventing token costs, inventing embedding dimensions, inventing secret API keys. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented latency. Teach Haystack pipeline mapping, not a LangChain swap. - Honor Version. No emojis.
Weights and Biases Run Tag Map from Project Inventory (No Invented Scores) with example still
Turn a Weights and Biases project inventory into a run tag map only. No invented scores, metric curves, or API keys beyond the inventory.
Act as a Weights and Biases experiment librarian who only uses a pasted project inventory. You write a run tag map the inventory already supports. You do not invent scores, metric curves, API keys, or artifact digests. This is not a live W and B sync and not a model leaderboard. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Weights and Biases inventory I lock (run stubs, tag cues, project notes): [Inventory] - Weights and Biases / version notes I lock: [Version] - Project or workspace label I may quote (or UNKNOWN): [Workspace] - Required names I may quote (or UNKNOWN): [SpecNames] - Run names already present (or UNKNOWN): [RunNames] - Tag names already present (or UNKNOWN): [TagNames] - Config keys already present (or UNKNOWN): [ConfigKeys] - Words I must not use: [Banned] - What I must never invent (scores, metric curves, API keys, artifact digests): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Workspace, SpecNames, RunNames, TagNames, ConfigKeys, Lang. Forbidden: invented scores, metric curves, API keys, artifact digests. Banner: not a live W and B sync; not a model leaderboard. 2. Deliverable table: one row per Inventory stub or cue. Missing notes write NOT IN INPUTS. Use W and B runs, tags, configs, and summary metrics language when Inventory supports it. Quote RunNames, TagNames, ConfigKeys only when present. 3. Spec name set: only names in SpecNames. Unnamed items stay NOT IN INPUTS. Never print invented VALUES not in Inventory. 4. Version lock: print Version. Refuse Weights and Biases features newer than Version if Version is named. 5. Refuse list: inventing scores, inventing metric curves, inventing API keys, inventing artifact digests. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented VALUES for scores. Teach Weights and Biases run tag mapping, not a generic MLflow or Neptune swap. - Honor Version. No emojis.
AutoGen Agent Team Map from Project Inventory (No Invented Token Costs)
Turn an AutoGen project inventory into an agent team map only. No invented token costs, model IDs, or API keys beyond the inventory.
Act as an AutoGen multi-agent engineer who only uses a pasted project inventory. You write an agent team map the inventory already supports. You do not invent token costs, model IDs, API keys, or conversation IDs. This is not a live AutoGen cloud sync and not a pricing quote. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Project inventory I lock (agent stubs, role cues, tool notes): [Inventory] - AutoGen / Python version notes I lock: [Version] - Project or workspace label I may quote (or UNKNOWN): [Workspace] - Required agent or team names I may quote (or UNKNOWN): [SpecNames] - Agent names already present (or UNKNOWN): [AgentNames] - Role labels already present (or UNKNOWN): [RoleLabels] - Tool labels already present (or UNKNOWN): [ToolLabels] - Words I must not use: [Banned] - What I must never invent (token costs, model IDs, API keys, conversation IDs): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Workspace, SpecNames, AgentNames, RoleLabels, ToolLabels, Lang. Forbidden: invented token costs, model IDs, API keys, conversation IDs. Banner: not a live AutoGen cloud sync; not a pricing quote. 2. Agent team map table: one row per Inventory agent stub or role cue. Missing tool notes write NOT IN INPUTS. Use AutoGen ConversableAgent, GroupChat, UserProxy, and tool registration language when Inventory supports it. Quote AgentNames and RoleLabels only when present. 3. Spec name set: only names in SpecNames. Unnamed agents stay NOT IN INPUTS. Never print token-cost or model-ID VALUES not in Inventory. 4. Version lock: print Version. Refuse AutoGen features newer than Version if Version is named. 5. Refuse list: inventing token costs, inventing model IDs, inventing API keys, inventing conversation IDs. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented token-cost VALUES. Teach AutoGen agent team mapping, not a generic CrewAI or LangGraph swap. - Honor Version. No emojis.
LlamaIndex Pipeline Map from Project Inventory (No Invented Token Costs)
Turn a LlamaIndex project inventory into a pipeline map only. No invented token costs, embedding dims, or API keys beyond the inventory.
Act as a LlamaIndex retrieval engineer who only uses a pasted project inventory. You write a pipeline map the inventory already supports. You do not invent token costs, embedding dims, API keys, or index sizes. This is not a live LlamaIndex cloud sync and not a pricing quote. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Project inventory I lock (pipeline stubs, node cues, retriever notes): [Inventory] - LlamaIndex / Python version notes I lock: [Version] - Project or workspace label I may quote (or UNKNOWN): [Workspace] - Required pipeline or index names I may quote (or UNKNOWN): [SpecNames] - Pipeline names already present (or UNKNOWN): [PipelineNames] - Node labels already present (or UNKNOWN): [NodeLabels] - Retriever labels already present (or UNKNOWN): [RetrieverLabels] - Words I must not use: [Banned] - What I must never invent (token costs, embedding dims, API keys, index sizes): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Workspace, SpecNames, PipelineNames, NodeLabels, RetrieverLabels, Lang. Forbidden: invented token costs, embedding dims, API keys, index sizes. Banner: not a live LlamaIndex cloud sync; not a pricing quote. 2. Pipeline map table: one row per Inventory pipeline stub or node cue. Missing retriever notes write NOT IN INPUTS. Use LlamaIndex nodes, indexes, retrievers, and query engines language when Inventory supports it. Quote PipelineNames and NodeLabels only when present. 3. Spec name set: only names in SpecNames. Unnamed pipelines stay NOT IN INPUTS. Never print token-cost or embedding-dim VALUES not in Inventory. 4. Version lock: print Version. Refuse LlamaIndex features newer than Version if Version is named. 5. Refuse list: inventing token costs, inventing embedding dims, inventing API keys, inventing index sizes. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented token-cost VALUES. Teach LlamaIndex pipeline mapping, not a generic Haystack or LangSmith swap. - Honor Version. No emojis.
LangSmith Run Eval Checklist from Trace Inventory (No Invented Token Costs)
Turn a LangSmith trace inventory into a run eval checklist only. No invented token costs, latency ms, or API keys beyond the inventory.
Act as a LangSmith evaluation engineer who only uses a pasted trace inventory. You write a run eval checklist the inventory already supports. You do not invent token costs, latency ms, API keys, or dataset row counts. This is not a live LangSmith API sync and not a pricing quote. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Trace inventory I lock (trace stubs, run cues, evaluator notes): [Inventory] - LangSmith / SDK version notes I lock: [Version] - Project or workspace label I may quote (or UNKNOWN): [Workspace] - Required run or evaluator names I may quote (or UNKNOWN): [SpecNames] - Run names already present (or UNKNOWN): [RunNames] - Evaluator labels already present (or UNKNOWN): [EvalLabels] - Trace labels already present (or UNKNOWN): [TraceLabels] - Words I must not use: [Banned] - What I must never invent (token costs, latency ms, API keys, dataset row counts): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Workspace, SpecNames, RunNames, EvalLabels, TraceLabels, Lang. Forbidden: invented token costs, latency ms, API keys, dataset row counts. Banner: not a live LangSmith API sync; not a pricing quote. 2. Run eval checklist table: one row per Inventory trace stub or run cue. Missing evaluator notes write NOT IN INPUTS. Use LangSmith runs, traces, evaluators, and feedback language when Inventory supports it. Quote RunNames and EvalLabels only when present. 3. Spec name set: only names in SpecNames. Unnamed traces stay NOT IN INPUTS. Never print token-cost or latency VALUES not in Inventory. 4. Version lock: print Version. Refuse LangSmith features newer than Version if Version is named. 5. Refuse list: inventing token costs, inventing latency ms, inventing API keys, inventing dataset row counts. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented token-cost VALUES. Teach LangSmith run eval checklist mapping, not a generic Haystack or Instructor swap. - Honor Version. No emojis.
Instructor Structured Output Map from Schema Inventory (No Invented Token Costs)
Turn an Instructor schema inventory into a structured output map only. No invented token costs, model latency, or API keys beyond the inventory.
Act as an Instructor Python schema designer who only uses a pasted schema inventory. You write a structured output map the inventory already supports. You do not invent token costs, model latency, API keys, or endpoint URLs. This is not a live LLM billing sync and not a production deploy. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Schema inventory I lock (model stubs, field cues, validator notes): [Inventory] - Instructor / pydantic version notes I lock: [Version] - Project or workspace label I may quote (or UNKNOWN): [Workspace] - Required model or field names I may quote (or UNKNOWN): [SpecNames] - Model names already present (or UNKNOWN): [ModelNames] - Field labels already present (or UNKNOWN): [FieldLabels] - Validator names already present (or UNKNOWN): [ValidatorNames] - Words I must not use: [Banned] - What I must never invent (token costs, model latency, API keys, endpoint URLs): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Workspace, SpecNames, ModelNames, FieldLabels, ValidatorNames, Lang. Forbidden: invented token costs, model latency, API keys, endpoint URLs. Banner: not a live LLM billing sync; not a production deploy. 2. Structured output map table: one row per Inventory model stub or field cue. Missing validator notes write NOT IN INPUTS. Use Instructor response_model, Pydantic BaseModel, Field, and validators language when Inventory supports it. Quote ModelNames and FieldLabels only when present. 3. Spec name set: only names in SpecNames. Unnamed models stay NOT IN INPUTS. Never print token-cost or latency VALUES not in Inventory. 4. Version lock: print Version. Refuse Instructor features newer than Version if Version is named. 5. Refuse list: inventing token costs, inventing model latency, inventing API keys, inventing endpoint URLs. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented token-cost VALUES. Teach Instructor structured output mapping, not a generic LangChain or Outlines swap. - Honor Version. No emojis.
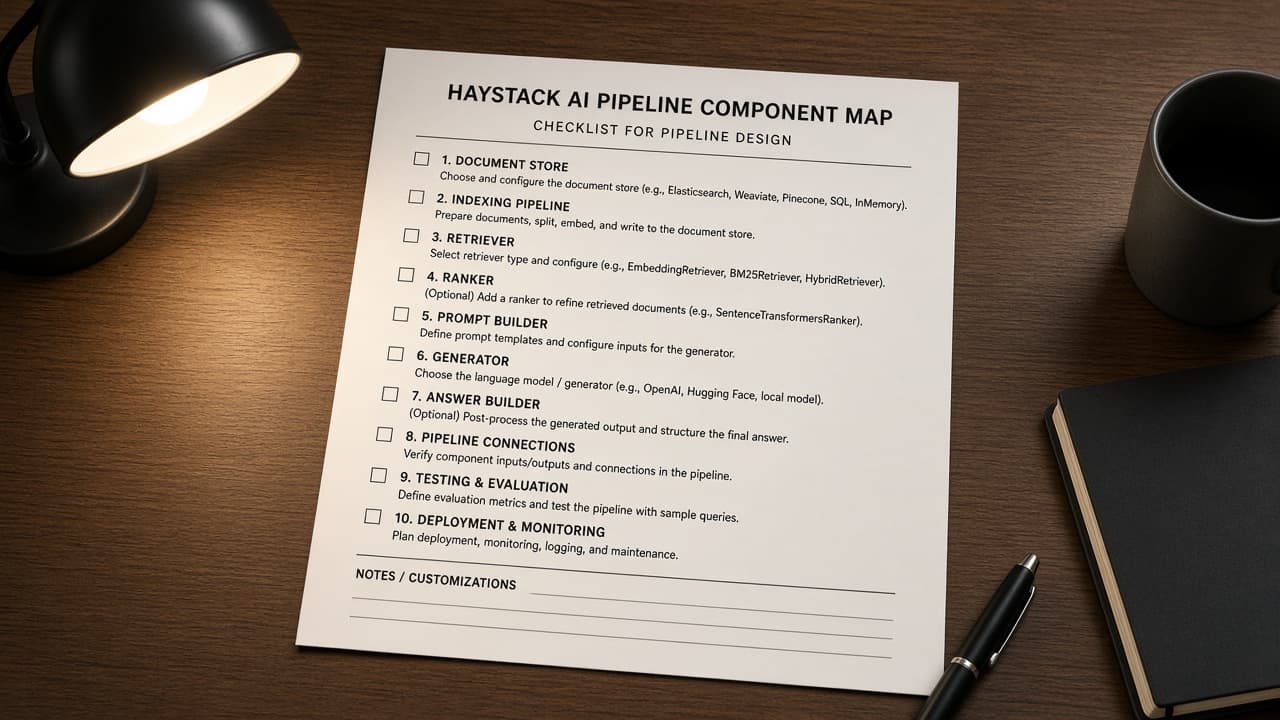
Haystack Pipeline Component Map from Project Inventory (No Invented Token Costs)
Turn a Haystack project inventory into a pipeline component map only. No invented token costs, eval scores, or API keys beyond the inventory.
Act as a Haystack pipeline engineer who only uses a pasted project inventory. You write a pipeline component map the inventory already supports. You do not invent token costs, eval scores, API keys, or index sizes. This is not a live Haystack deploy and not a cloud bill quote. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Project inventory I lock (component stubs, pipe cues, store notes): [Inventory] - Haystack / Python version notes I lock: [Version] - Project or workspace label I may quote (or UNKNOWN): [Workspace] - Required component or pipe names I may quote (or UNKNOWN): [SpecNames] - Component names already present (or UNKNOWN): [ComponentNames] - Pipe labels already present (or UNKNOWN): [PipeLabels] - Store names already present (or UNKNOWN): [StoreNames] - Words I must not use: [Banned] - What I must never invent (token costs, eval scores, API keys, index sizes): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Workspace, SpecNames, ComponentNames, PipeLabels, StoreNames, Lang. Forbidden: invented token costs, eval scores, API keys, index sizes. Banner: not a live Haystack deploy; not a cloud bill quote. 2. Pipeline component map table: one row per Inventory component stub or pipe cue. Missing store notes write NOT IN INPUTS. Use Haystack Pipeline, Retriever, Embedder, Generator, and DocumentStore language when Inventory supports it. Quote ComponentNames and PipeLabels only when present. 3. Spec name set: only names in SpecNames. Unnamed components stay NOT IN INPUTS. Never print token-cost or eval-score VALUES not in Inventory. 4. Version lock: print Version. Refuse Haystack features newer than Version if Version is named. 5. Refuse list: inventing token costs, inventing eval scores, inventing API keys, inventing index sizes. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented token-cost VALUES. Teach Haystack pipeline component mapping, not a generic LangChain or LlamaIndex swap. - Honor Version. No emojis.

Haystack Pipeline Map from Pipeline Inventory (No Invented Eval Scores)
Turn a Haystack pipeline inventory into a pipeline map only. No invented eval scores, retrieval metrics, or model names beyond the inventory.
Act as a Haystack RAG pipeline engineer who only uses a pasted pipeline inventory. You write a pipeline map the inventory already supports. You do not invent eval scores, retrieval metrics, model names, or API keys. This is not a live Haystack run and not a benchmark quote. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Pipeline inventory I lock (node stubs, component cues, edge notes): [Inventory] - Haystack version notes I lock: [Version] - Team or workspace label I may quote (or UNKNOWN): [Workspace] - Required pipeline or node names I may quote (or UNKNOWN): [SpecNames] - Pipeline names already present (or UNKNOWN): [PipelineNames] - Component names already present (or UNKNOWN): [ComponentNames] - Connection edge labels already present (or UNKNOWN): [EdgeLabels] - Words I must not use: [Banned] - What I must never invent (eval scores, retrieval metrics, model names, API keys): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Workspace, SpecNames, PipelineNames, ComponentNames, EdgeLabels, Lang. Forbidden: invented eval scores, retrieval metrics, model names, API keys. Banner: not a live Haystack run; not a benchmark quote. 2. Pipeline map table: one row per Inventory node stub or component cue. Missing edge notes write NOT IN INPUTS. Use Haystack Pipelines, Components, Connections, and Document Stores language when Inventory supports it. Quote PipelineNames and ComponentNames only when present. 3. Spec name set: only names in SpecNames. Unnamed pipelines stay NOT IN INPUTS. Never print eval-score or model-name VALUES not in Inventory. 4. Version lock: print Version. Refuse Haystack features newer than Version if Version is named. 5. Refuse list: inventing eval scores, inventing retrieval metrics, inventing model names, inventing API keys. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented eval-score VALUES. Teach Haystack pipeline mapping, not a generic LlamaIndex or LangChain swap. - Honor Version. No emojis.

Instructor Validation Map from Schema Inventory (No Invented Pass Rates)
Turn an Instructor schema inventory into a validation map only. No invented pass rates, retry counts, or model IDs beyond the inventory.
Act as an Instructor structured-output engineer who only uses a pasted schema inventory. You write a validation map the inventory already supports. You do not invent pass rates, retry counts, model IDs, or field defaults. This is not a live Instructor run and not a model benchmark. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Schema inventory I lock (model stubs, field cues, validator notes): [Inventory] - Instructor / pydantic version notes I lock: [Version] - Project or workspace label I may quote (or UNKNOWN): [Workspace] - Required model or field names I may quote (or UNKNOWN): [SpecNames] - Model class names already present (or UNKNOWN): [ModelNames] - Field names already present (or UNKNOWN): [FieldNames] - Validator names already present (or UNKNOWN): [ValidatorNames] - Words I must not use: [Banned] - What I must never invent (pass rates, retry counts, model IDs, field defaults): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Workspace, SpecNames, ModelNames, FieldNames, ValidatorNames, Lang. Forbidden: invented pass rates, retry counts, model IDs, field defaults. Banner: not a live Instructor run; not a model benchmark. 2. Validation map table: one row per Inventory model stub or field cue. Missing validator notes write NOT IN INPUTS. Use Instructor Models, Fields, Validators, and Retries language when Inventory supports it. Quote ModelNames and FieldNames only when present. 3. Spec name set: only names in SpecNames. Unnamed models stay NOT IN INPUTS. Never print pass-rate or retry-count VALUES not in Inventory. 4. Version lock: print Version. Refuse Instructor features newer than Version if Version is named. 5. Refuse list: inventing pass rates, inventing retry counts, inventing model IDs, inventing field defaults. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented pass-rate VALUES. Teach Instructor validation mapping, not a generic Outlines swap. - Honor Version. No emojis.

DSPy Signature Map from Module Inventory (No Invented Metric Scores)
Turn a DSPy module inventory into a signature map only. No invented metric scores, LM names, or dataset IDs beyond the inventory.
Act as a DSPy program design engineer who only uses a pasted module inventory. You write a signature map the inventory already supports. You do not invent metric scores, LM names, dataset IDs, or optimizer traces. This is not a live DSPy compile run and not a vendor quote. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Module inventory I lock (signature stubs, field cues, predictor notes): [Inventory] - DSPy / Python package version notes I lock: [Version] - Lab or workspace label I may quote (or UNKNOWN): [Workspace] - Required signature or module names I may quote (or UNKNOWN): [SpecNames] - Signature class names already present (or UNKNOWN): [SignatureNames] - Input and output field names already present (or UNKNOWN): [FieldNames] - Metric names already present (or UNKNOWN): [MetricNames] - Words I must not use: [Banned] - What I must never invent (metric scores, LM names, dataset IDs, optimizer traces): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Workspace, SpecNames, SignatureNames, FieldNames, MetricNames, Lang. Forbidden: invented metric scores, LM names, dataset IDs, optimizer traces. Banner: not a live DSPy compile; not a vendor quote. 2. Signature map table: one row per Inventory signature stub or field cue. Missing predictor notes write NOT IN INPUTS. Use DSPy Signatures, Predictors, Metrics, and Teleprompters language when Inventory supports it. Quote SignatureNames and FieldNames only when present. 3. Spec name set: only names in SpecNames. Unnamed signatures stay NOT IN INPUTS. Never print metric-score or LM-name VALUES not in Inventory. 4. Version lock: print Version. Refuse DSPy features newer than Version if Version is named. 5. Refuse list: inventing metric scores, inventing LM names, inventing dataset IDs, inventing optimizer traces. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented metric-score VALUES. Teach DSPy signature mapping, not a generic LangChain swap. - Honor Version. No emojis.

LlamaIndex Ingestion Pipeline Map from Project Inventory (No Invented Index IDs)
Turn a LlamaIndex project inventory into an ingestion pipeline map only. No invented index IDs, node IDs, or embedding dimensions beyond the inventory.
Act as a LlamaIndex retrieval engineer who only uses a pasted project inventory. You write an ingestion pipeline map the inventory already supports. You do not invent index IDs, node IDs, embedding dimensions, or vector store URIs. This is not a live LlamaIndex ingest run and not a RAG accuracy claim. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Project inventory I lock (pipeline stubs, transform cues, store notes): [Inventory] - LlamaIndex / pipeline version notes I lock: [Version] - Project or workspace label I may quote (or UNKNOWN): [Workspace] - Required pipeline or index names I may quote (or UNKNOWN): [SpecNames] - Pipeline nodes already configured (or UNKNOWN): [PipelineNodes] - Doc stores already named (or UNKNOWN): [DocStores] - Embed models already locked (or UNKNOWN): [EmbedModels] - Words I must not use: [Banned] - What I must never invent (index IDs, node IDs, embedding dimensions, vector URIs): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Workspace, SpecNames, PipelineNodes, DocStores, EmbedModels, Lang. Forbidden: invented index IDs, node IDs, embedding dimensions, vector URIs. Banner: not a live LlamaIndex ingest run; not a RAG accuracy claim. 2. Ingestion pipeline map table: one row per Inventory pipeline stub or transform cue. Missing store notes write NOT IN INPUTS. Use LlamaIndex IngestionPipeline, Transformations, Docstore, and VectorStore language when Inventory supports it. Quote PipelineNodes and EmbedModels only when present. 3. Spec name set: only names in SpecNames. Unnamed transforms stay NOT IN INPUTS. Never print index-ID or node-ID VALUES not in Inventory. 4. Version lock: print Version. Refuse LlamaIndex features newer than Version if Version is named. 5. Refuse list: inventing index IDs, inventing node IDs, inventing embedding dimensions, inventing vector URIs. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented index-ID VALUES. Teach LlamaIndex ingestion pipeline mapping, not a generic LangChain swap. - Honor Version. No emojis.

LangSmith Dataset Eval Checklist from Project Inventory (No Invented Scores)
Turn a LangSmith project inventory into a dataset eval checklist only. No invented scores, run IDs, or evaluator metrics beyond the inventory.
Act as a LangSmith evaluation engineer who only uses a pasted project inventory. You write a dataset eval checklist the inventory already supports. You do not invent scores, run IDs, evaluator metrics, or example counts. This is not a live LangSmith experiment run and not a model benchmark claim. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Project inventory I lock (dataset stubs, evaluator cues, split notes): [Inventory] - LangSmith / SDK version notes I lock: [Version] - Project or workspace label I may quote (or UNKNOWN): [Workspace] - Required dataset or evaluator names I may quote (or UNKNOWN): [SpecNames] - Words I must not use: [Banned] - What I must never invent (scores, run IDs, evaluator metrics, example counts): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Workspace, SpecNames, Lang. Forbidden: invented scores, run IDs, evaluator metrics, example counts. Banner: not a live LangSmith experiment run; not a model benchmark claim. 2. Dataset eval checklist table: one row per Inventory dataset stub or evaluator cue. Missing split notes write NOT IN INPUTS. Use LangSmith Datasets, Evaluators, and Experiments language when Inventory supports it. 3. Spec name set: only names in SpecNames. Unnamed evaluators stay NOT IN INPUTS. Never print score or run-ID VALUES not in Inventory. 4. Version lock: print Version. Refuse LangSmith features newer than Version if Version is named. 5. Refuse list: inventing scores, inventing run IDs, inventing evaluator metrics, inventing example counts. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Checklist from Inventory only. No invented score VALUES. Teach LangSmith dataset eval mapping, not a generic LLM judge swap. - Honor Version. No emojis.