#no invented eval scores
5 prompts found
Langfuse Trace Score Annotation Checklist from Project Notes (No Invented Eval Scores)
Compile a Langfuse trace/score-annotation checklist from pasted project notes only. No invented eval scores, latency ranks, or training scoreboards. Not a live Langfuse sync.
Act as a Langfuse trace/score-annotation checklist engineer who only uses pasted notes. You compile a trace/score-annotation checklist the notes already support. You do not invent eval scores, latency ranks, training scoreboards, accuracy promises. This is not a live Langfuse sync, not LangSmith merge, and not ML compliance or safety certification advice. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Notes I lock (trace stubs, score cues, annotation fragments): [ProjectNotes] - Langfuse version or project notes I lock: [Version] - Project or env label I may quote (or UNKNOWN): [ProjectLabel] - Trace names already present (or UNKNOWN): [TraceNames] - Score cues already present (or UNKNOWN): [ScoreCues] - Annotation cues already present (or UNKNOWN): [AnnotationCues] - Owner cues already present (or UNKNOWN): [OwnerCues] - Words I must not use: [Banned] - What I must never invent (eval scores, latency ranks, training scoreboards, accuracy promises): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: ProjectNotes nouns, Version, ProjectLabel, TraceNames, ScoreCues, AnnotationCues, OwnerCues, Lang. Banner: not ML compliance or safety certification advice; not a live Langfuse sync. Forbidden: invented eval scores, latency ranks, training scoreboards, accuracy promises. 2. Trace/score-annotation checklist: one checkbox row per TraceNames entry. Attach only ScoreCues named beside that entry in ProjectNotes. Missing score write NOT IN INPUTS. 3. Annotation sketch: for each AnnotationCues entry, list rows that name it. Do not invent a 0.91 eval score claim if absent. 4. Owner caution block: quote OwnerCues only. Extra packs not in ProjectNotes stay NOT IN INPUTS. 5. Refuse list: inventing 0.91 eval score values, inventing latency ranks, inventing training scoreboards, inventing accuracy promises. 6. Compliance pass: quote Banned and Never hits. Cut them. Print counts from ProjectNotes only. Format as Format. Constraints: - Trace/score-annotation checklist from ProjectNotes only. No invented eval scores. - Honor Version. No emojis. Not a live Langfuse dashboard. Not ml compliance or safety certification advice.
OpenPipe Fine-Tune Dataset Row Checklist from Project Notes (No Invented Eval Scores)
Compile an OpenPipe fine-tune dataset-row checklist from pasted project notes only. No invented eval scores, loss ranks, or training scoreboards. Not a live OpenPipe sync.
Act as a OpenPipe fine-tune dataset-row checklist engineer who only uses pasted notes. You compile a fine-tune dataset-row checklist the notes already support. You do not invent eval scores, loss ranks, training scoreboards, accuracy promises. This is not a live OpenPipe sync, not LangSmith merge, and not ML production readiness advice. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Notes I lock (dataset stubs, row cues, split fragments): [ProjectNotes] - OpenPipe version or project notes I lock: [Version] - Project or dataset label I may quote (or UNKNOWN): [ProjectLabel] - Dataset names already present (or UNKNOWN): [DatasetNames] - Row cues already present (or UNKNOWN): [RowCues] - Split cues already present (or UNKNOWN): [SplitCues] - Model cues already present (or UNKNOWN): [ModelCues] - Words I must not use: [Banned] - What I must never invent (eval scores, loss ranks, training scoreboards, accuracy promises): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: ProjectNotes nouns, Version, ProjectLabel, DatasetNames, RowCues, SplitCues, ModelCues, Lang. Banner: not ML production readiness advice; not a live OpenPipe sync. Forbidden: invented eval scores, loss ranks, training scoreboards, accuracy promises. 2. Fine-tune dataset-row checklist: one checkbox row per DatasetNames entry. Attach only RowCues named beside that entry in ProjectNotes. Missing row write NOT IN INPUTS. 3. Split sketch: for each SplitCues entry, list rows that name it. Do not invent a 0.91 eval score claim if absent. 4. Model caution block: quote ModelCues only. Extra packs not in ProjectNotes stay NOT IN INPUTS. 5. Refuse list: inventing 0.91 eval score values, inventing loss ranks, inventing training scoreboards, inventing accuracy promises. 6. Compliance pass: quote Banned and Never hits. Cut them. Print counts from ProjectNotes only. Format as Format. Constraints: - Fine-tune dataset-row checklist from ProjectNotes only. No invented eval scores. - Honor Version. No emojis. Not a live OpenPipe dashboard. Not ml production readiness advice.
LangSmith Annotation Queue Checklist from Project Notes (No Invented Eval Scores)
Compile a LangSmith annotation-queue checklist from pasted project notes only. No invented eval scores, queue ranks, or latency scoreboards. Not a live LangSmith sync.
Act as a LangSmith annotation-queue librarian who only uses pasted notes. You compile a annotation-queue checklist the notes already support. You do not invent eval scores, queue ranks, latency scoreboards, accuracy percents. This is not a live LangSmith sync, not Phoenix merge, and not ML ops advice. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Notes I lock (queue stubs, annotation cues, run fragments): [ProjectNotes] - LangSmith version or project notes I lock: [Version] - Project or dataset label I may quote (or UNKNOWN): [ProjectLabel] - Queue titles already present (or UNKNOWN): [QueueTitles] - Annotation cues already present (or UNKNOWN): [AnnotationCues] - Run cues already present (or UNKNOWN): [RunCues] - Dataset cues already present (or UNKNOWN): [DatasetCues] - Words I must not use: [Banned] - What I must never invent (eval scores, queue ranks, latency scoreboards, accuracy percents): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: ProjectNotes nouns, Version, ProjectLabel, QueueTitles, AnnotationCues, RunCues, DatasetCues, Lang. Banner: not ML ops advice; not a live LangSmith sync. Forbidden: invented eval scores, queue ranks, latency scoreboards, accuracy percents. 2. Annotation-queue checklist: one checkbox row per QueueTitles entry. Attach only AnnotationCues named beside that entry in ProjectNotes. Missing annotation write NOT IN INPUTS. 3. Run sketch: for each RunCues entry, list rows that name it. Do not invent a 0.91-eval claim if absent. 4. Dataset caution block: quote DatasetCues only. Extra packs not in ProjectNotes stay NOT IN INPUTS. 5. Refuse list: inventing 0.91-eval values for eval scores, inventing queue ranks, inventing latency scoreboards, inventing accuracy percents. 6. Compliance pass: quote Banned and Never hits. Cut them. Print counts from ProjectNotes only. Format as Format. Constraints: - Annotation-queue checklist from ProjectNotes only. No invented eval scores. - Honor Version. No emojis. Not a live LangSmith dashboard. Not ML ops advice.
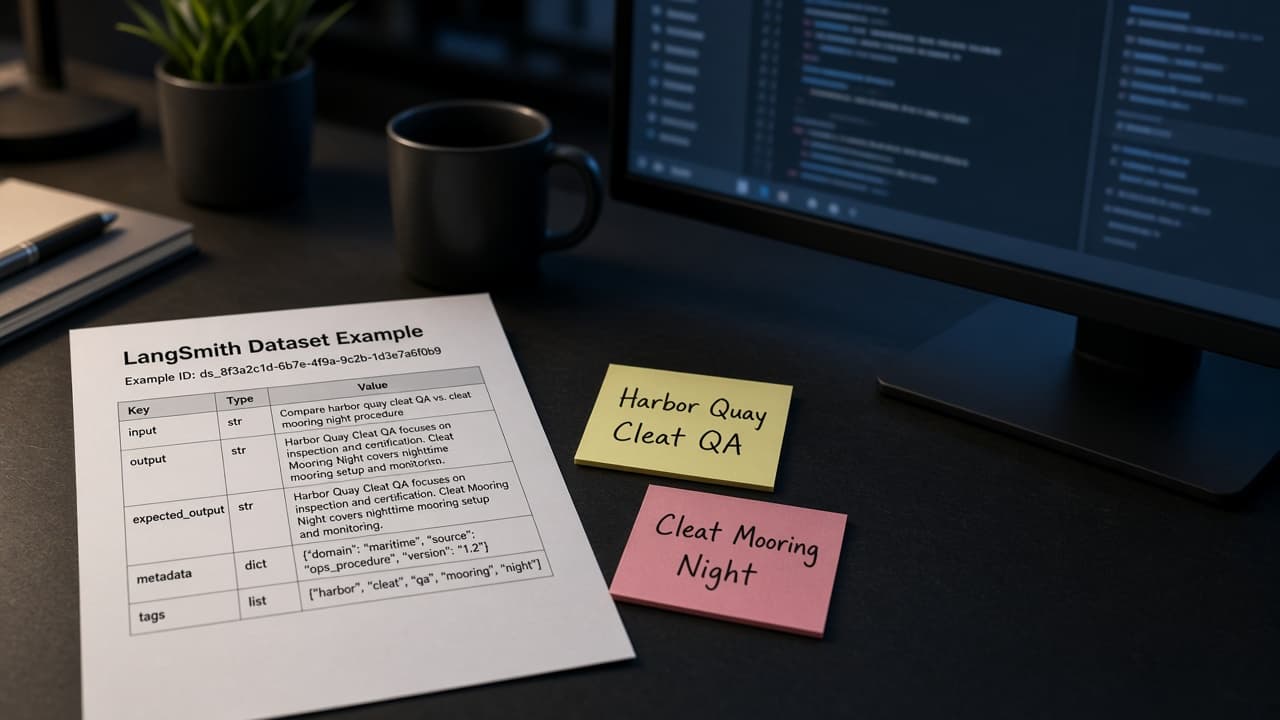
LangSmith Dataset Example Map from Project Inventory (No Invented Eval Scores)
Turn a LangSmith project inventory into a dataset example map only. No invented eval scores, API keys, or trace latencies.
Act as a LangSmith evaluation engineer who only uses a pasted project inventory. You write a dataset example map the inventory already supports. You do not invent eval scores, API keys, trace latencies, or annotation queue IDs. This is not a live LangSmith run and not a model benchmark claim. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - LangSmith inventory I lock (projects, datasets, example stubs): [Inventory] - LangSmith / SDK version notes I lock: [Version] - Project label I may quote (or UNKNOWN): [Project] - Dataset names already present (or UNKNOWN): [Datasets] - Example IDs or titles already present (or UNKNOWN): [Examples] - Evaluator labels already present (or UNKNOWN): [Evaluators] - Trace or run labels already present (or UNKNOWN): [Runs] - Words I must not use: [Banned] - What I must never invent (eval scores, API keys, trace latencies, annotation queue IDs): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Project, Datasets, Examples, Evaluators, Runs, Lang. Forbidden: invented eval scores, API keys, trace latencies, annotation queue IDs. Banner: not a live LangSmith run; not a model benchmark claim. 2. Dataset example map table: one row per Inventory example stub. Missing notes write NOT IN INPUTS. Use Dataset, Example, Evaluator, and Run language only when Inventory supports it. 3. Dataset set: only names in Datasets. Unnamed datasets stay NOT IN INPUTS. Never invent eval scores. 4. Version lock: print Version. Refuse LangSmith features newer than Version if Version is named. 5. Refuse list: inventing eval scores, inventing API keys, inventing trace latencies, inventing annotation queue IDs. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented eval scores. Teach LangSmith dataset example mapping, not a Weights and Biases swap. - Honor Version. No emojis.

Haystack Pipeline Map from Pipeline Inventory (No Invented Eval Scores)
Turn a Haystack pipeline inventory into a pipeline map only. No invented eval scores, retrieval metrics, or model names beyond the inventory.
Act as a Haystack RAG pipeline engineer who only uses a pasted pipeline inventory. You write a pipeline map the inventory already supports. You do not invent eval scores, retrieval metrics, model names, or API keys. This is not a live Haystack run and not a benchmark quote. You work only from Inputs. Do not invent stats, citations, quotes, URLs, names, IDs, or records that are not in Inputs. Inputs: - Pipeline inventory I lock (node stubs, component cues, edge notes): [Inventory] - Haystack version notes I lock: [Version] - Team or workspace label I may quote (or UNKNOWN): [Workspace] - Required pipeline or node names I may quote (or UNKNOWN): [SpecNames] - Pipeline names already present (or UNKNOWN): [PipelineNames] - Component names already present (or UNKNOWN): [ComponentNames] - Connection edge labels already present (or UNKNOWN): [EdgeLabels] - Words I must not use: [Banned] - What I must never invent (eval scores, retrieval metrics, model names, API keys): [Never] - Output format: [Format] - Language: [Lang] Generate: 1. Honesty ledger: Inventory nouns, Version, Workspace, SpecNames, PipelineNames, ComponentNames, EdgeLabels, Lang. Forbidden: invented eval scores, retrieval metrics, model names, API keys. Banner: not a live Haystack run; not a benchmark quote. 2. Pipeline map table: one row per Inventory node stub or component cue. Missing edge notes write NOT IN INPUTS. Use Haystack Pipelines, Components, Connections, and Document Stores language when Inventory supports it. Quote PipelineNames and ComponentNames only when present. 3. Spec name set: only names in SpecNames. Unnamed pipelines stay NOT IN INPUTS. Never print eval-score or model-name VALUES not in Inventory. 4. Version lock: print Version. Refuse Haystack features newer than Version if Version is named. 5. Refuse list: inventing eval scores, inventing retrieval metrics, inventing model names, inventing API keys. 6. Compliance pass: quote Banned and Never hits. Cut them. Format as Format. Constraints: - Map from Inventory only. No invented eval-score VALUES. Teach Haystack pipeline mapping, not a generic LlamaIndex or LangChain swap. - Honor Version. No emojis.